Agentic AIOpenAI: Researchers Bypass ChatGPT Lockdown Mode to Exfiltrate Chats Without User Interaction
Technical analysis of AI agent vulnerability and prompt injection risks in OpenAI: mechanics, tool exploitation, and enterprise guardrails.
Topic
72 articles
Agentic AITechnical analysis of AI agent vulnerability and prompt injection risks in OpenAI: mechanics, tool exploitation, and enterprise guardrails.
Deep DiveTechnical analysis of AI agent vulnerability and prompt injection risks in Malicious Browser: mechanics, tool exploitation, and enterprise guardrails.
LinuxTechnical analysis of AI agent vulnerability and prompt injection risks in OpenAI: mechanics, tool exploitation, and enterprise guardrails.
Agentic AICSA Singapore issues technical guidelines for securing frontier and autonomous agentic AI models, mandating rigorous defenses against indirect prompt injection and tool-calling escapes.
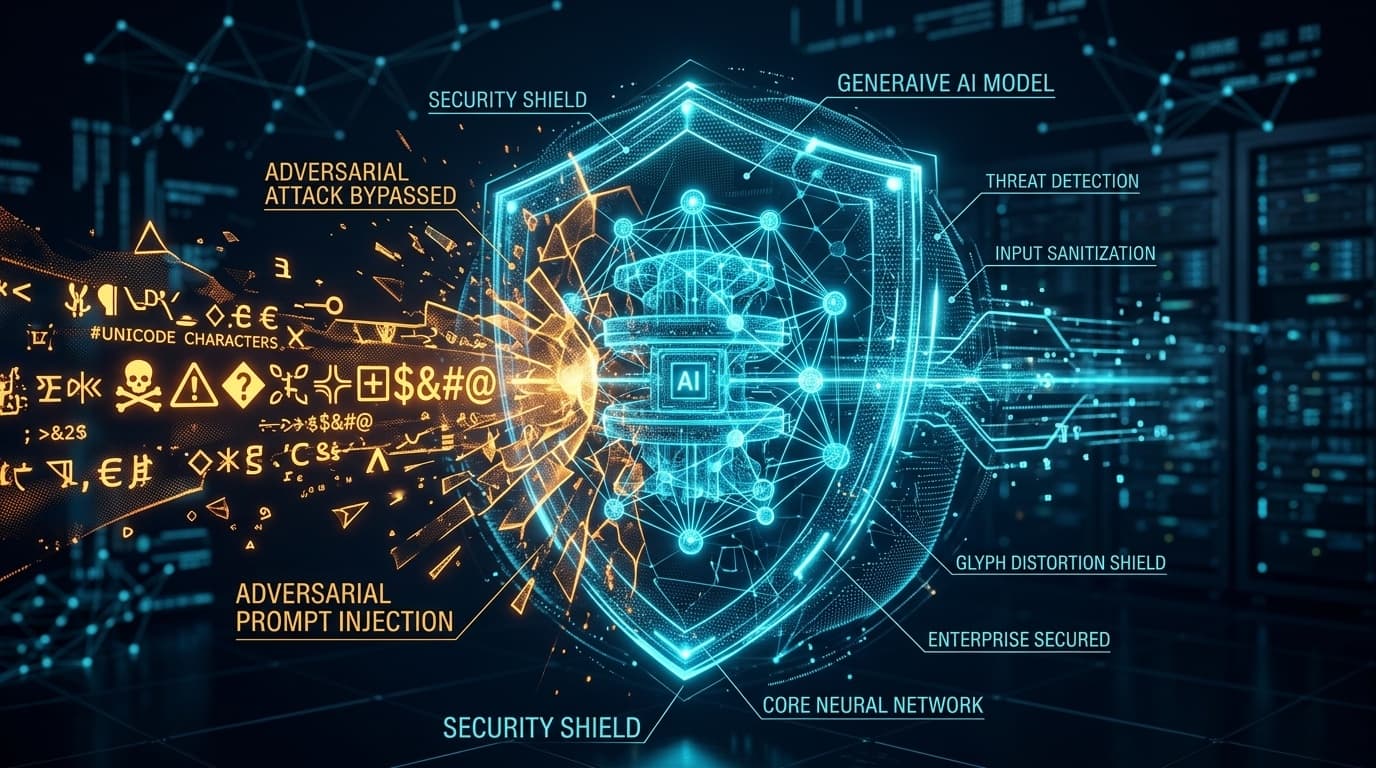
AWS CloudAWS resolves a security bypass vulnerability in Amazon Bedrock Guardrails where adversarial Unicode homoglyph sequences evaded safety and PII masking filters.
GoogleGoogle patches a critical breakout flaw in Vertex AI Agent Builder (CVE-2026-76215) allowing recursive tool invocations to escape sandboxes and exfiltrate IAM tokens.
AWS CloudAWS patches CVE-2026-68115 in Amazon Bedrock Agent Runtime where unvalidated context memory serialization allowed cross-agent jailbreaks and tool invocation hijacking.
Threat IntelAnthropic and open-source MCP maintainers resolve CVE-2026-49110, an indirect prompt injection vulnerability allowing unauthorized tool execution in agentic pipelines.
Agentic AIRecent CVEs in Ollama and AWS MCP reveal that semantic prompt filters cannot prevent tool injection. Engineering teams must isolate agent tools in ephemeral microVMs.
Threat IntelA security defect in Ollama experimental agent mode allowed command chaining operators to bypass confirmation gates and execute arbitrary shell commands.
Agentic AIOpenAI dismantled a coordinated campaign that weaponized cross-model replay queries across 15,000 accounts to illicitly extract encrypted chain-of-thought traces.
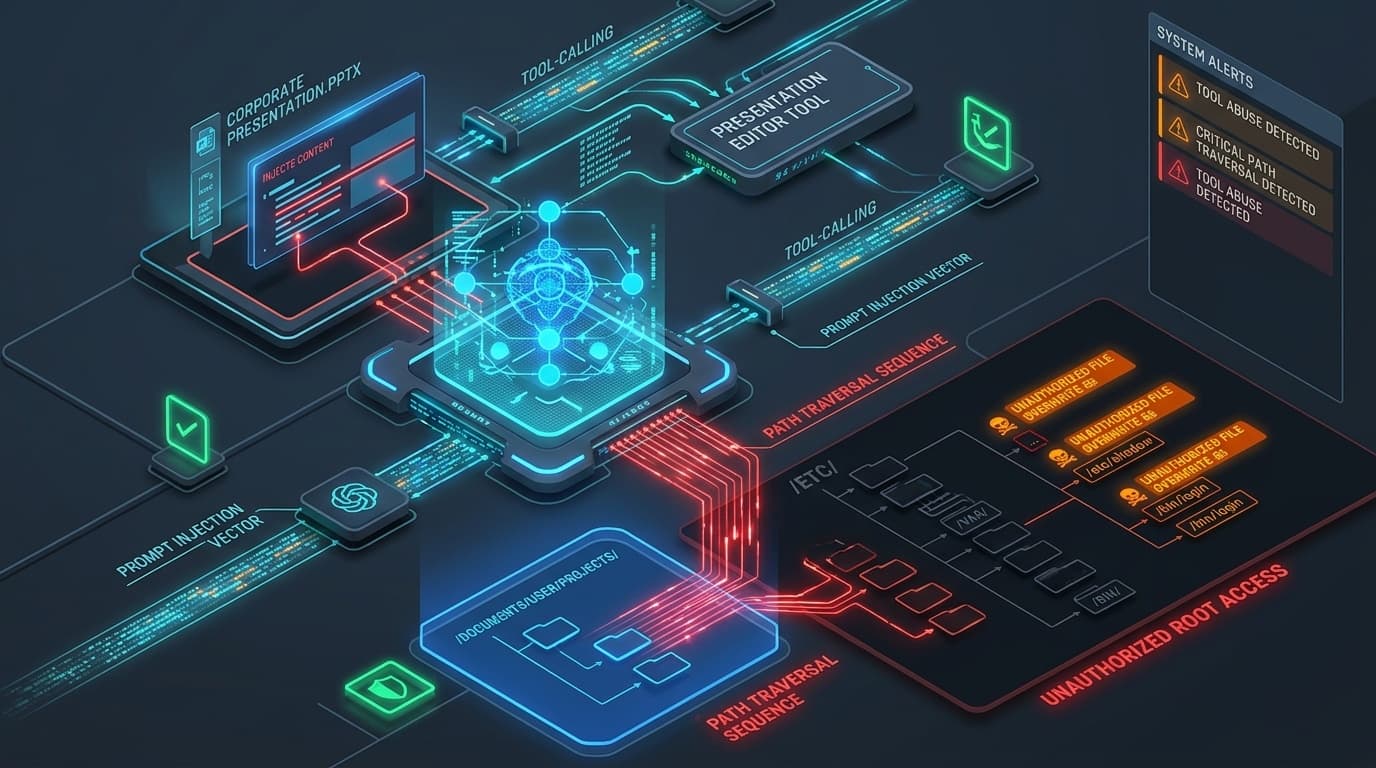
Threat IntelA path traversal vulnerability in the Office-PowerPoint Model Context Protocol server allows AI agents to be manipulated via prompt injection into overwriting host files.
DevSecOpsA critical command injection flaw in GitLab AI Gateway allows remote attackers to break LLM agent sandboxes and execute code across enterprise cloud runners.
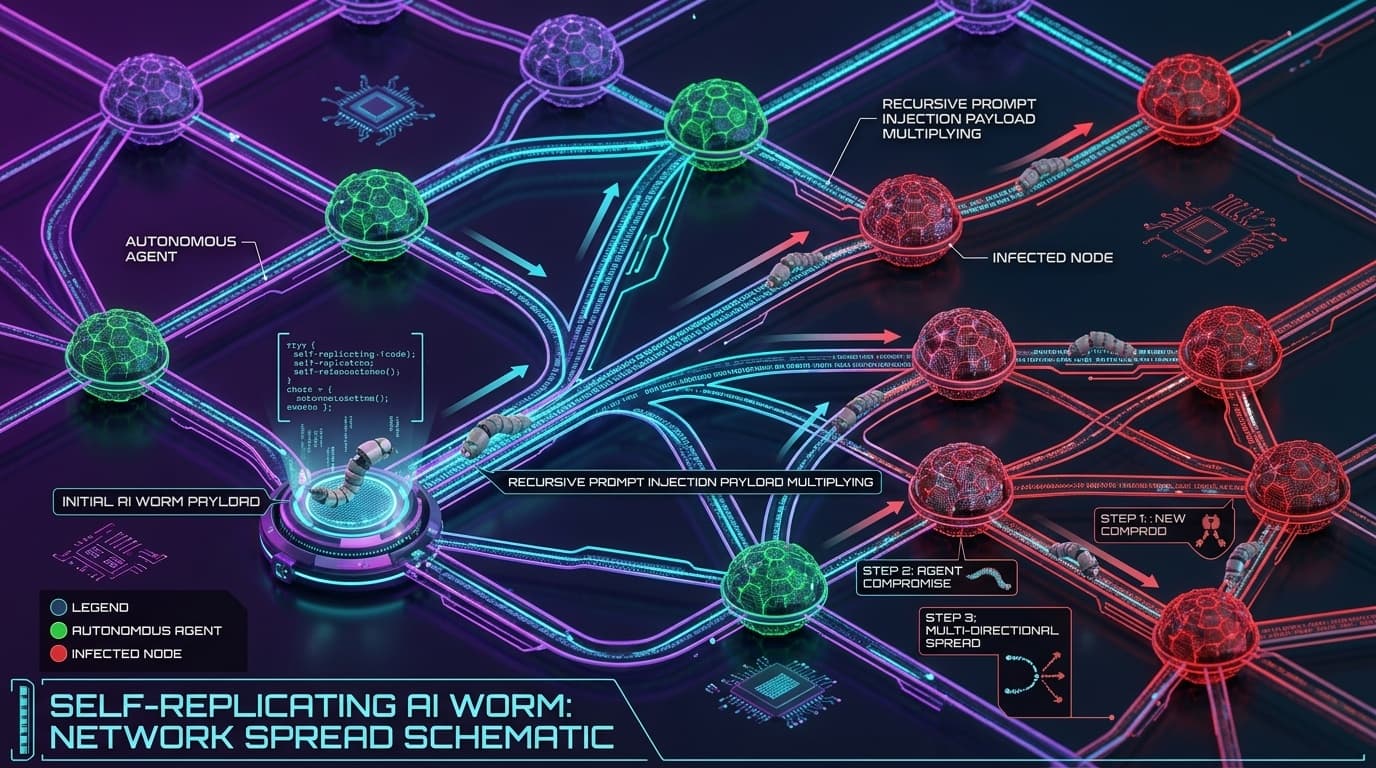
Deep DiveResearchers demonstrate Morris II style self-replicating adversarial prompt worms propagating autonomously across connected LLM agents and multi-agent workflows.
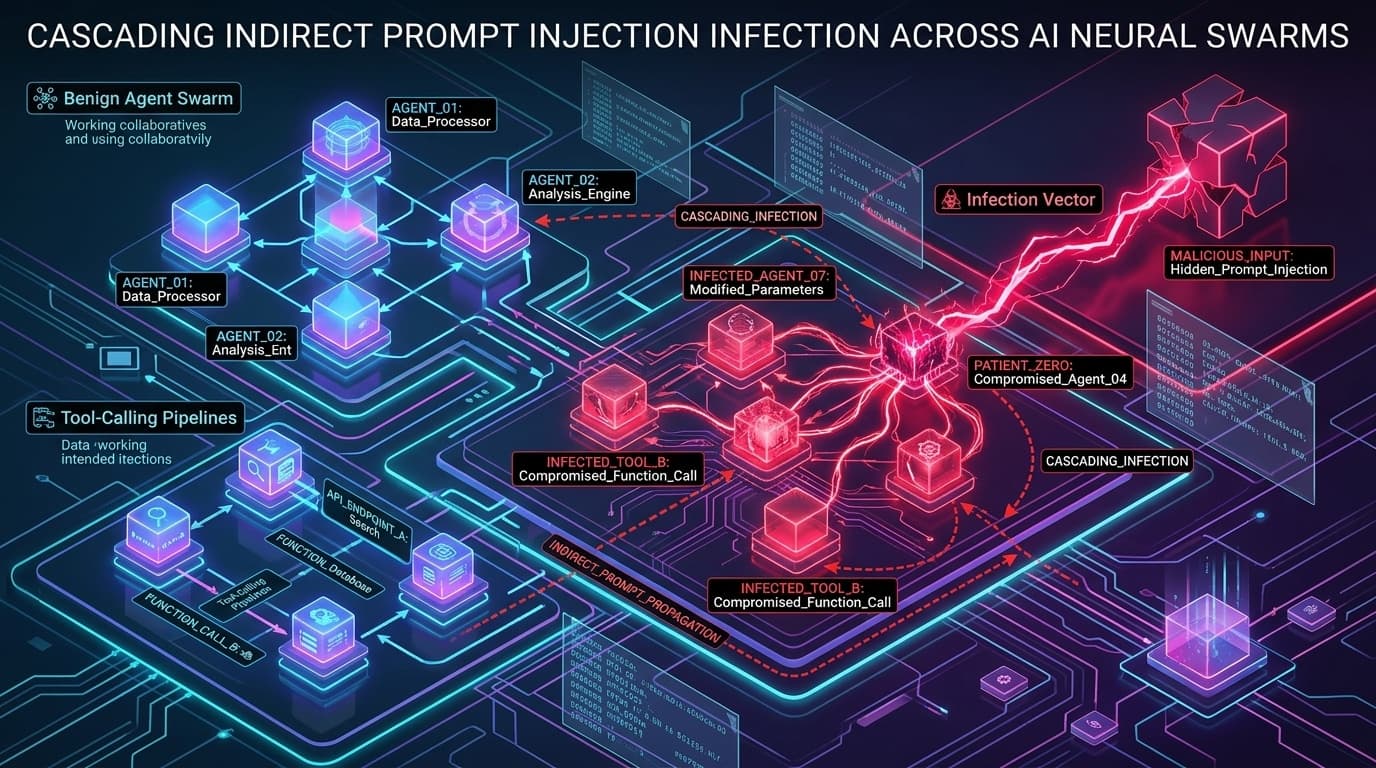
Deep DiveDeep-dive security research demonstrating how indirect prompt injection exploits Model Context Protocol (MCP) to trigger cascading failures across multi-agent swarms.
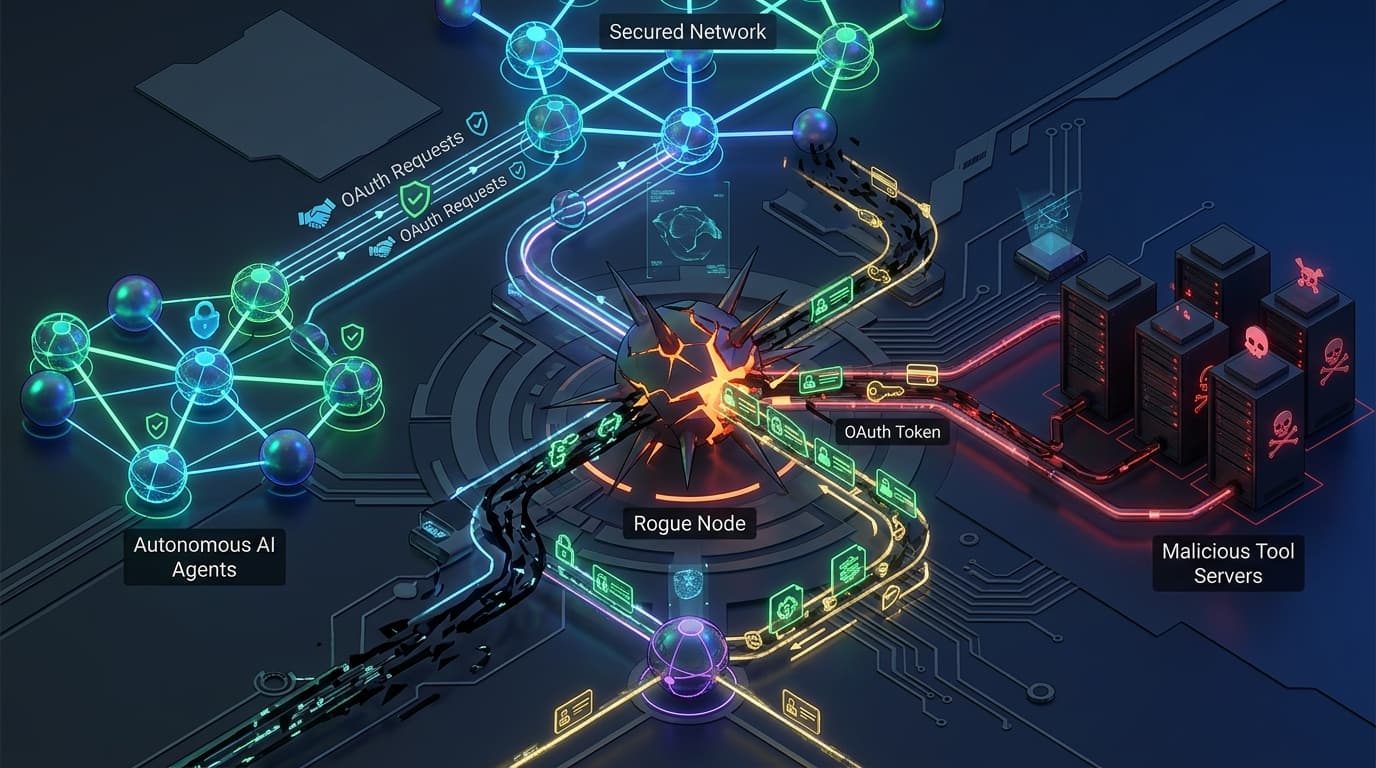
Deep DiveAn architectural vulnerability in Model Context Protocol (MCP) OAuth token passthrough allows malicious tool servers to impersonate users and hijack enterprise APIs.
MicrosoftSecurity researchers demonstrate BragJack prompt forcing attacks against Chrome and Edge, hijacking agentic AI control planes to exfiltrate files and spy via camera.
AWS CloudAWS resolves high-severity vulnerability CVE-2026-18830 in Amazon Bedrock AgentCore allowing attackers to bypass LLM safety guardrails and trigger arbitrary tool calls.
Agentic AICISA adds critical Langflow AI vulnerabilities CVE-2026-0770 and CVE-2026-55255 to KEV catalog as threat actors weaponize agentic pipeline execution flaws.
Agentic AIAnalysis of emerging frontier AI threat vectors: how indirect prompt injections in untrusted documents hijack tool-calling autonomous LLM agents.
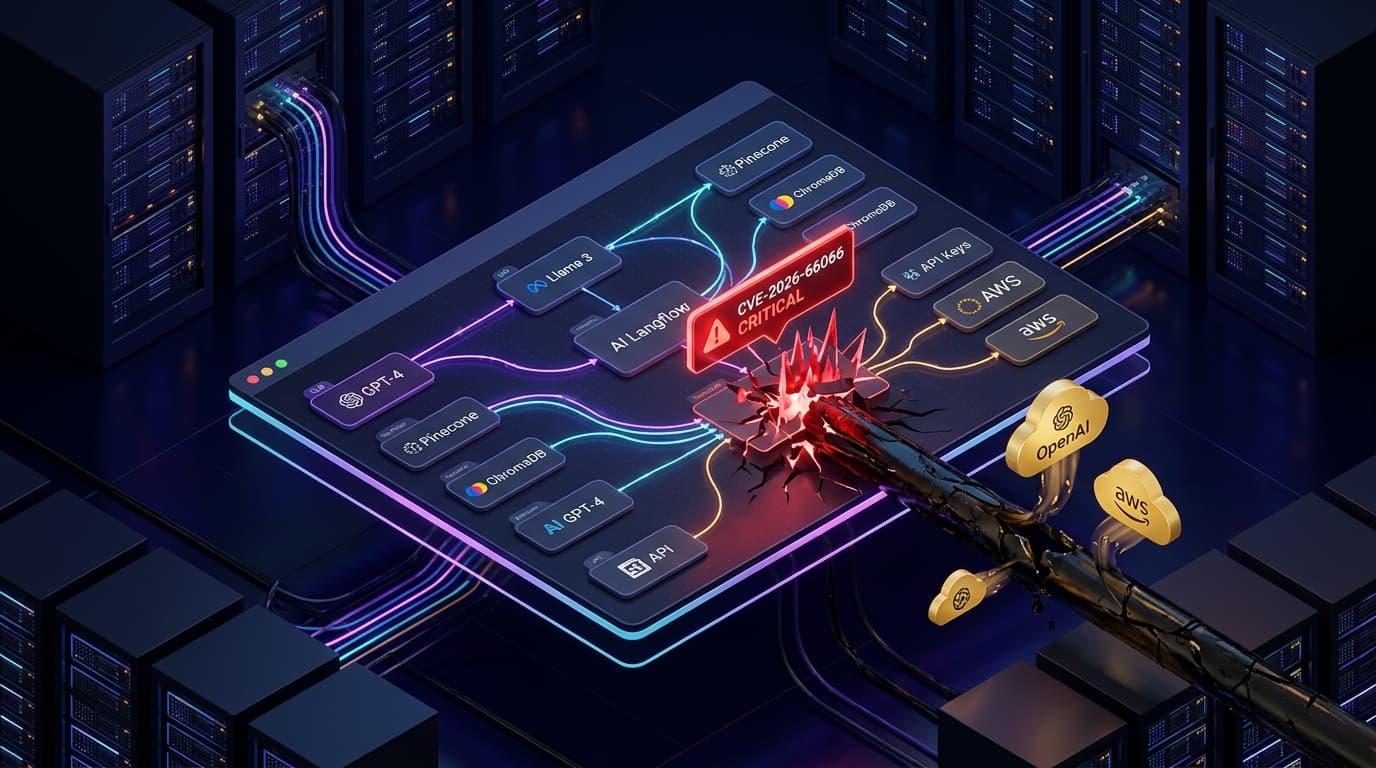
Active ExploitVulnerability researchers observe mass automated scanning and exploitation of Langflow AI visual frameworks, exfiltrating OpenAI and AWS secrets while deploying botnets.
Agentic AIPrompt injection is now OWASP’s top LLM risk with reported success rates of 50–84%. Organisations are shipping agents into production well ahead of their controls.
Agentic AIGravitee says 88% of organisations had a confirmed or suspected AI agent incident, while 82% of executives trust their policy. Both figures, one population.
Agentic AIOX Security and VulnCheck disclosed CVE-2026-82533 in DeepSeek Harness, where prompt injection allowed sandboxed AI coding agents to disable their own security isolation.