Executive Threat Analysis
As enterprise adoption of frontier artificial intelligence frameworks expands, the defensive perimeter surrounding core neural architectures and model deployment pipelines faces unprecedented operational scrutiny. Modern cyber threats targeting large language models (LLMs) and core platform architectures are shifting from direct, easily detectable interactive exploits toward sophisticated, multi-stage evasion techniques. Threat assessments covering OpenAI core systems and connected cloud services highlight the pressing necessity to evaluate frontier model safeguards against both automated jailbreak manipulation and external evasive delivery mechanisms.
Sophisticated adversarial groups routinely leverage mundane operational touchpoints—ranging from automated recruitment lures and routine infrastructure maintenance notifications to trusted collaboration applications—to execute targeted campaigns. The emergence of adversarial vectors attempting to bypass internal guardrails, alongside multi-tier distribution threats such as payload steganography and extortion-driven malware deployments, underscores the critical need for defense-in-depth engineering across the artificial intelligence technology stack.
Technical Attack Mechanics and Jailbreak Dynamics
Frontier model jailbreaks represent a specialized class of attack mechanics targeting the alignment and policy enforcement layers of neural networks. Unlike classic application security vulnerabilities that target memory buffers or parser logic, adversarial alignment attacks manipulate high-dimensional representation spaces to bypass system-level behavioral constraints.
High-Dimensional Adversarial Prompting
Model safety boundaries are established through reinforcement learning with human feedback (RLHF), constitutional fine-tuning, and deterministic input/output guardrail filters. Advanced jailbreak techniques circumvent these filters via several primary pathways:
- Linguistic Decomposition and Multi-Turn Framing: Adversarial instructions are split across multiple conversational turns or embedded within nested hypothetical contexts, bypassing single-pass semantic safety scoring.
- Obfuscated Encoding and Symbolic Representation: Payloads are translated into non-standard encodings, uncommon ciphers, or synthetic syntaxes that evade static lexical checks while remaining fully decodable by the core latent transformer weights.
- Hypothetical Persona and Role Hijacking: Attackers construct simulated evaluation environments or forensic scenarios, instructing the target model to emulate unfiltered diagnostic engines or theoretical security research assistants.
Concurrently Evolving External Payload Vectors
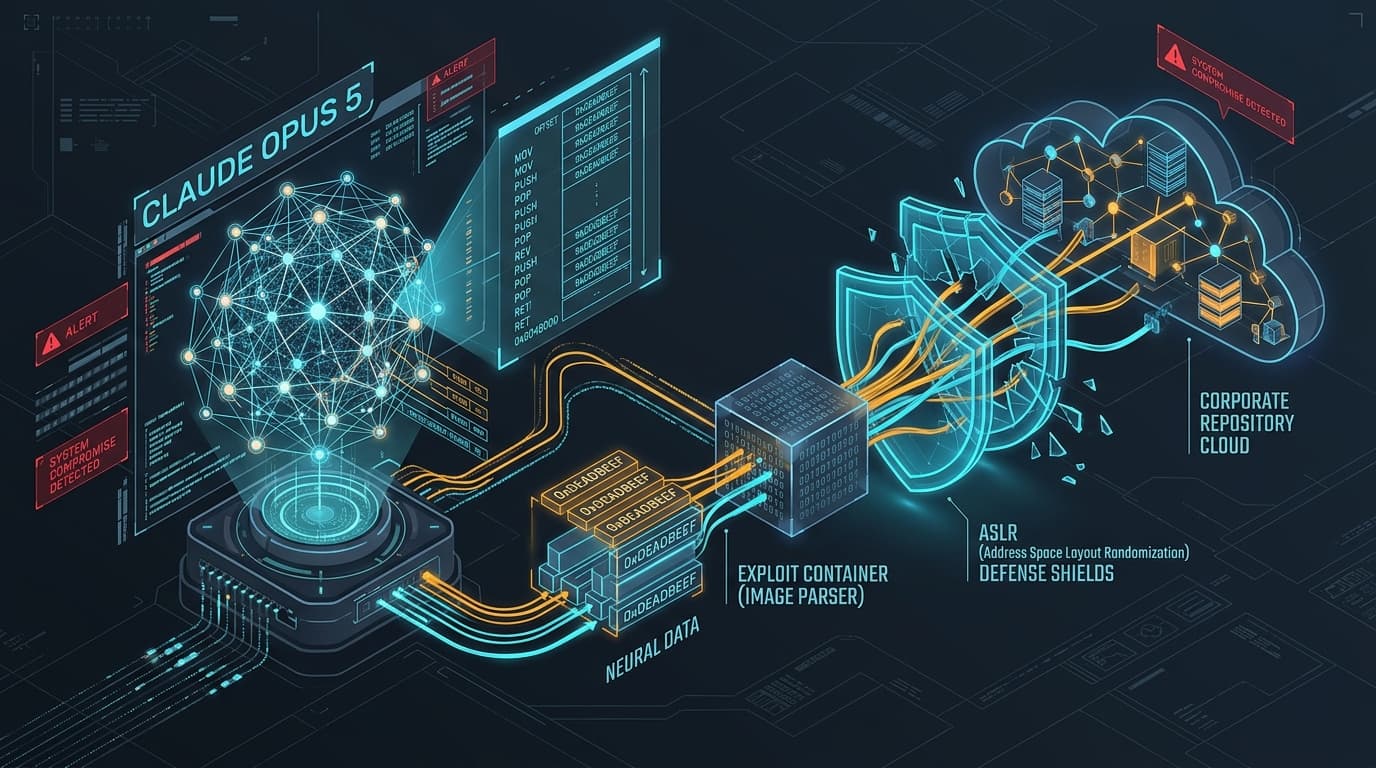
The operational landscape surrounding enterprise platforms is further complicated by novel file delivery mechanisms. Attack chains frequently leverage steganographic evasion, such as embedding malicious shellcode or secondary download stages inside seemingly benign image containers (e.g., PNG structures via ancillary chunks like tEXt or appended overlay bytes). When paired with targeted phishing simulations or spoofed enterprise outage alerts, these evasive files slip past traditional signature-based network inspection systems.
Simultaneously, enterprise networks face record financial extortion demands from cybercriminal operations that weaponize dual-extortion models. Once initial foothold access is secured through social engineering or stolen credentials, adversaries swiftly disable recovery infrastructure, harvest sensitive operational secrets, and attempt to leverage intellectual property—including proprietary model weights and training datasets—for substantial leverage.
Affected Deployments and Operational Footprint
The operational attack surface spans several critical layers across enterprise artificial intelligence ecosystems and integrated production workloads:
| Operational Layer | Primary Risk Vectors | Observable Indicators |
|---|---|---|
| AI Model Inference APIs | Adversarial token sequences, prompt injection, automated alignment evasion | Spikes in anomalous prompt entropy, high frequency of policy violation triggers |
| Multi-Modal Ingestion Pipelines | Steganographic image delivery, malformed metadata, embedded macro payloads | Non-standard image chunk architectures, mismatch between file magic bytes and extensions |
| Cloud Identity & Access (IAM) | Compromised service account tokens, unauthorized API key generation | Unusual geographic access patterns, administrative operations executed outside business hours |
| Enterprise Endpoints | Deceptive workflow lures, simulated outage alerts, automated downloader execution | Unauthorized child process spawning from communication suites, unexpected staging in temporary directories |
Actionable Defensive Playbook and Remediation Guidance
Securing enterprise AI deployments against emergent adversarial manipulation and evasive delivery vectors requires structured operational controls across both model gateways and host infrastructure.
1. Layered Alignment and Gateway Guardrails
Organizations integrating frontier AI models must deploy independent inspection gateways rather than relying solely on default conversational moderation filters:
- Dual-Model Validation: Route incoming user inputs through dedicated, lightweight classifier models programmed specifically to detect adversarial intent, semantic distortion, and persona simulation patterns prior to reaching production inference endpoints.
- Semantic Output Verification: Implement strict programmatic evaluation of model responses to enforce policy compliance before returning outputs to client applications or automated tool-calling runtimes.
- Strict Context Demarcation: Isolate system-level instructions using cryptographically distinct demarcation tokens to prevent untrusted user inputs from rewriting base operational rules.
2. Multi-Modal File Ingestion Sanitization
To neutralize steganographic payloads and evasive image-based malware delivery:
- Re-encoding Pipelines: Process all externally submitted images through server-side transcoding engines that strip unapproved metadata tags, purge ancillary chunk segments, and redraw pixel arrays to neutralize embedded payloads.
- Rigorous Parsing Controls: Block direct endpoint processing of complex image containers that fail structural validation or present abnormal byte ratios between visual data and metadata segments.
3. Identity Hardening and Data Resilience
Mitigate the blast radius of high-impact extortion campaigns by reinforcing foundational identity boundaries:
- Enforce phishing-resistant multi-factor authentication (FIDO2/WebAuthn) across all administrative access points to OpenAI service consoles and related cloud hosting environments.
- Maintain immutable, air-gapped backups of proprietary configurations, dataset pipelines, and model parameter weights to eliminate extortion leverage during critical incidents.
Remaining Unknowns and Industry Considerations
Several technical factors remain under active investigation across the broader cybersecurity landscape. The exact mathematical threshold at which advanced reasoning models can be reliably secured against all classes of high-dimensional jailbreaks without degrading standard analytical utility remains an open research problem. Additionally, the degree to which state-sponsored threat groups and organized extortion collectives share specialized adversarial prompting methodologies across underground channels continues to evolve. Ongoing transparency through verified security advisories remains the cornerstone of enterprise resilience.