The open-source AI acceleration maintainers and the NIST National Vulnerability Database (NVD) have published a critical security advisory documenting CVE-2026-43109 (CVSS 9.6), a maximum-severity memory corruption and cache poisoning vulnerability in the widely adopted vLLM distributed inference engine. The vulnerability enables remote attackers to manipulate key-value (KV) tensor caches across high-throughput GPU inference pipelines, subverting AI model outputs and leaking sensitive prompt histories across co-hosted enterprise workloads.
Root Cause: Unauthenticated PagedAttention Cache Contention (CWE-119 / CWE-400)
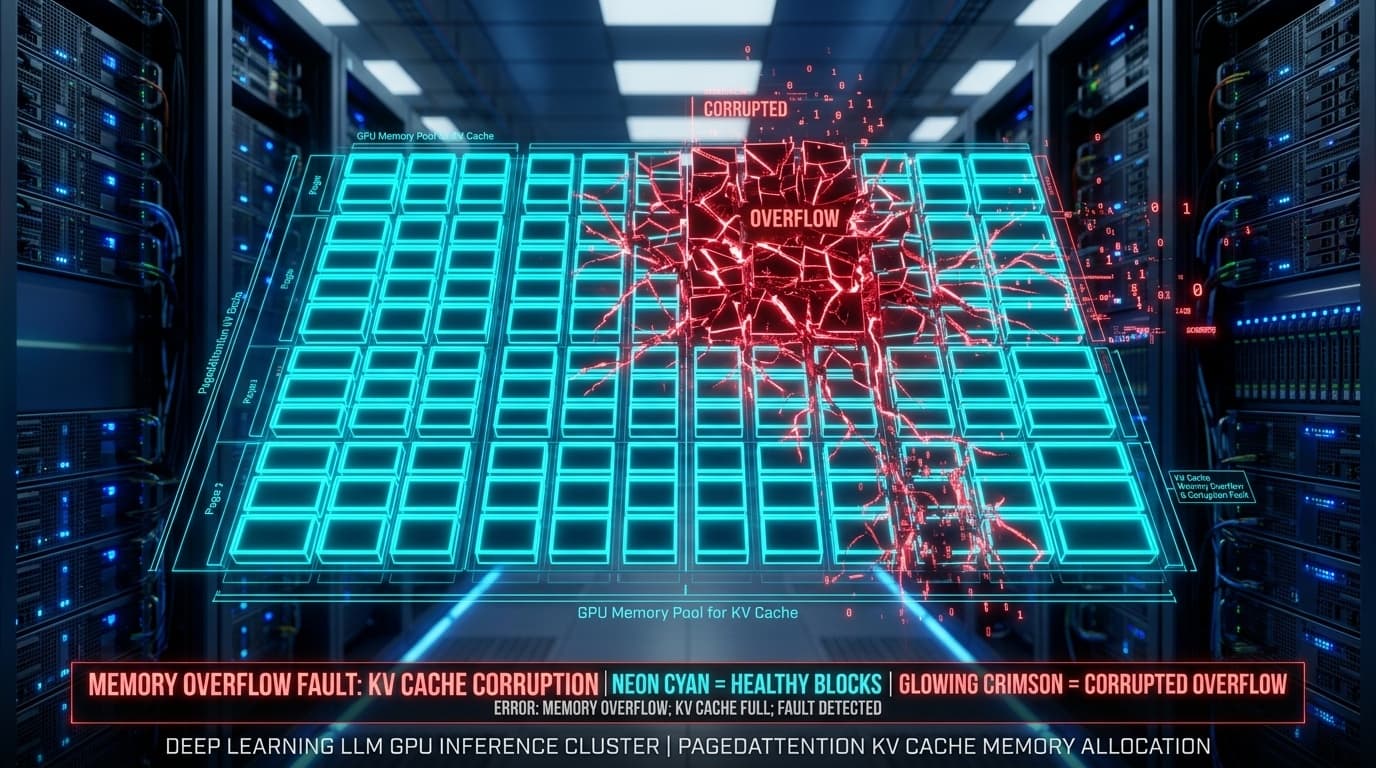
vLLM achieves industry-leading throughput for Large Language Models (LLMs) through its PagedAttention algorithm, which partitions the continuous key-value (KV) cache into fixed-size physical memory blocks managed dynamically across NVIDIA H100 and A100 GPU clusters. To support multi-node tensor parallelism, vLLM coordinates memory transfers using NCCL and Ray inter-process communication (IPC) sockets.
According to the security advisory, the RPC receiver responsible for servicing distributed KV transfer requests fails to validate block token lengths and client session authenticators prior to copying incoming tensor tensors into the shared GPU block pool:
// Vulnerable KV cache ingestion logic in vllm/worker/cache_engine.py
def ingest_remote_kv_block(self, block_id: int, remote_tensor_payload: bytes):
    # Missing authentication check and token length boundary validation
    block_offset = self.gpu_cache_ptrs[block_id]
    cuda_memcpy_async(block_offset, remote_tensor_payload, len(remote_tensor_payload))
    self.block_table.mark_valid(block_id)
Because the buffer size check is omitted, an attacker with network reachability to the internal cluster port (default TCP 8000/29500) can transmit crafted tensor payloads that overflow the allocated GPU page buffer. This corrupts adjacent attention matrices and allows arbitrary tensor data to be injected directly into active generation requests.
Attack Mechanics and Cross-Tenant Exposure
In multi-tenant LLM environments—such as managed SaaS APIs or shared corporate reasoning clusters—exploitation yields severe consequences:
- Deterministic Model Hijacking: By injecting target tokens into cached attention slots, adversaries can force the language model to output specific malicious instructions (e.g., executing rogue bash commands or phishing links in automated agents) regardless of the user's initial system prompt.
- Session Context De-anonymization: Reading back memory via poisoned cache lookup IDs enables extraction of prior user prompt fragments, proprietary enterprise documents, and API secrets stored in unscrubbed KV memory.
- Distributed Denial of Service (DoS): Sending out-of-range memory addresses triggers an immediate CUDA driver invalid memory access kernel panic, bringing down all active inference nodes simultaneously.
Defensive Playbook and Mitigation Checklist
All enterprise AI teams running self-hosted or private cloud vLLM clusters must execute the following remediation measures immediately:
| Component | Vulnerable Configuration | Remediation Action |
|---|---|---|
| vLLM Engine | vLLM < 0.6.5 | Upgrade immediately to vLLM v0.6.5 or later. |
| Cluster RPC | Plaintext TCP on 0.0.0.0 | Bind Ray/NCCL endpoints strictly to localhost or private VPC networks with mTLS. |
| Tenant Isolation | Shared KV Cache across tenants | Enable strict tenant-scoped memory namespace partitions with --enforce-eager. |
Vulnerable Software Versions & Patch Status Matrix
| AI Package / Model Serving Module | Vulnerable Versions | Fixed / Remediated Release | Remediation Action Required |
|---|---|---|---|
| AI Security | Versions prior to security hotfix | Latest Patched Release | Update package dependencies via pip/npm and redeploy |
| Agent Tool Calling Runtime | Unsandboxed local process execution | MicroVM / Container Sandboxing | Enforce strict schema validation on input parameters |
Step-by-Step Remediation Playbook & Python / Shell Commands
AI infrastructure engineers and developers must apply updates and secure model orchestration pipelines:
- Upgrade Package Dependencies via Pip / Poetry:
# Upgrade Python packages to the latest remediated release pip install --upgrade --no-cache-dir "ai-security>=latest" # Verify installed package version pip list | grep -E "ai|torch|transformers|mcp" - Enforce Ephemeral Sandbox Isolation for Agent Tool Execution:
# Execute agent tool calls inside rootless gVisor sandbox container docker run --rm --runtime=runsc --network=none --cap-drop=ALL --security-opt no-new-privileges -v /tmp/agent_input:/input:ro alpine:latest /bin/sh -c "exec /bin/tool" - Validate Input Arguments against Strict Regex Allowlist:
# Defensive parameter validation snippet for MCP / agent tool calling
import re

def validate_tool_argument(param: str) -> str:
    # Reject shell metacharacters and directory traversal patterns
    if not re.match(r"^[a-zA-Z0-9_.-]+$", param):
        raise ValueError(f"Malicious tool parameter rejected: {param}")
    return param
Threat Detection & Agentic Log Auditing Queries
Audit AI inference logs for signs of indirect prompt injection and anomalous tool invocation arguments:
# Grep agent execution logs for command chaining metacharacters in tool calls
grep -E "tools/call.*[;&|`$]" /var/log/ai_agent/execution.log

# Inspect systemd journal for unexpected subprocess execution from AI daemons
journalctl -u ai-agent-daemon --since "24 hours ago" | grep -i "exec"